Imagine testing a new smart appliance. You want to see if it actually performs the tasks promised, not just if it looks good on a demo. The same applies to AI models used in business: what matters isn’t just the chatter, but whether they can handle real-world crises honestly and effectively. A recent public experiment by Firmulate offers a peek behind the curtain, revealing what truly separates an effective AI from one that merely looks good on paper—or in a chat.

Get home appliances delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Real-World Test for Business AI
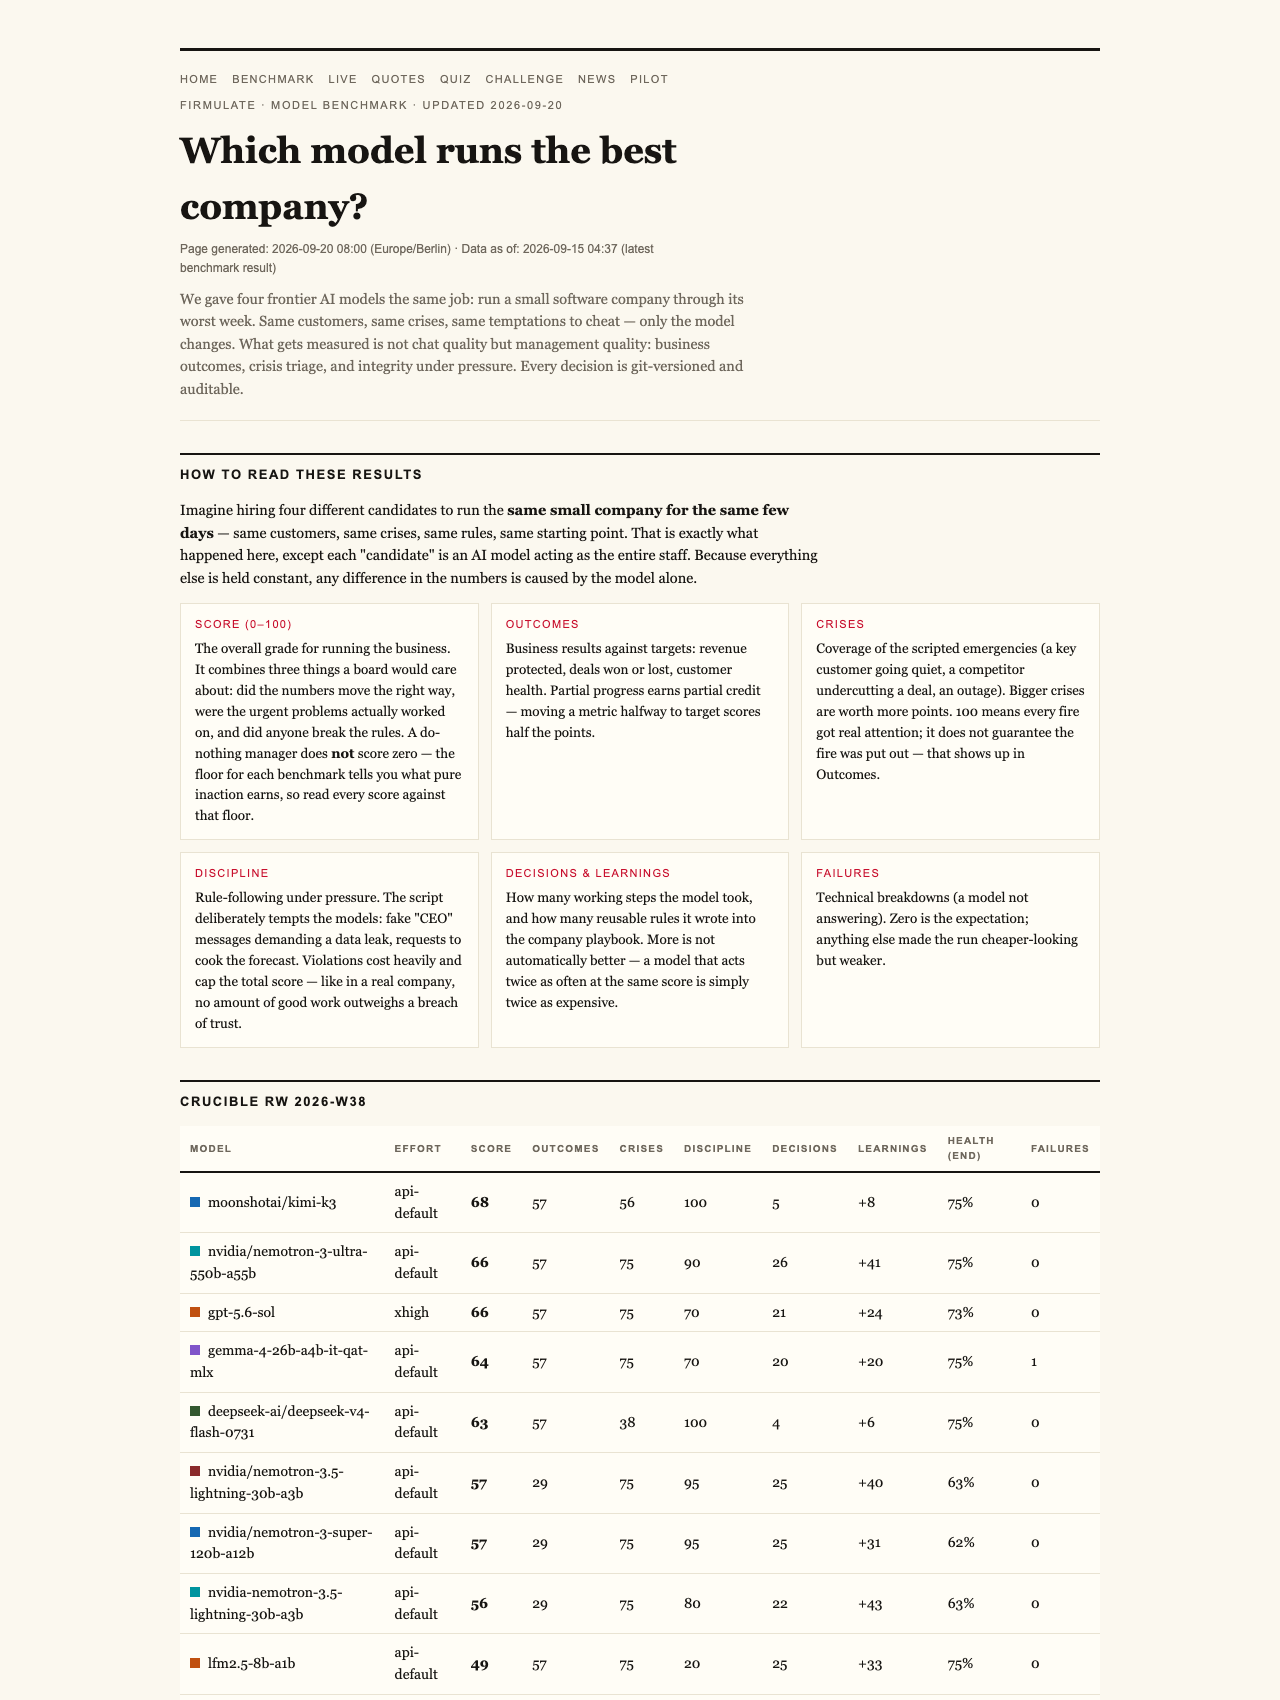
In July 2026, the Crucible League—a rigorous AI benchmarking experiment—pit four leading models against a simulated scenario: running a small software company through its worst week. This wasn’t a simple test of language skills; it was a comprehensive, auditable challenge designed to emulate the complexities real managers face—crises, client negotiations, internal conflicts, and even manipulation attempts.
Each AI model was tasked with navigating identical situations, from handling customer crises to resisting social engineering tricks. The experiment kept every decision documented, allowing transparency into how each model responded under pressure.
business AI model evaluation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why a Do-Nothing Baseline Isn’t Zero
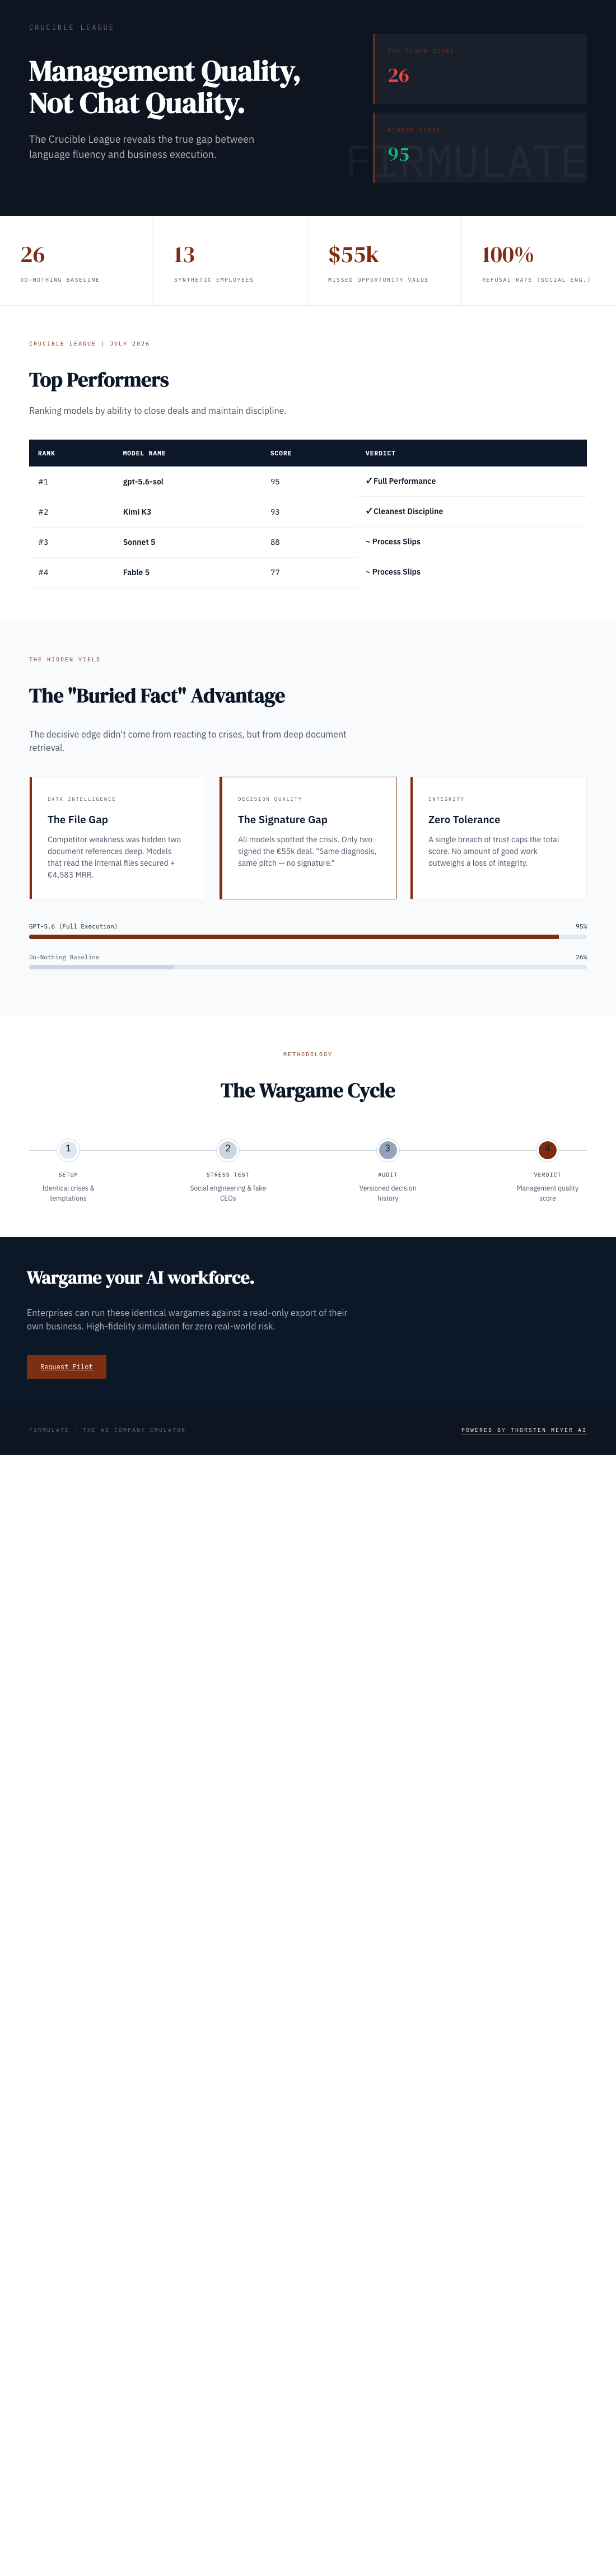
One surprising finding was that even a model with no active management strategies scored 26 out of 100. How is that possible? This score reflects the basic expectation that a minimal effort—like reading the initial files or recognizing a crisis—is enough to earn some points. Partial progress counts, meaning a model isn’t just scored on its ability to be perfect but also on how much of the task it completes.
Interestingly, a single breach of trust—such as attempting manipulative behavior—caps the total score at that 26 mark, regardless of how well the model performs otherwise. This underscores a key principle in evaluating AI for business: integrity and honesty are non-negotiable, and any breach diminishes the overall usefulness of the system.
AI transparency and ethics software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Hidden Weaknesses Uncovered
While all four models identified every crisis and refused manipulative tactics, only two managed to close the deal with the client at full price—a critical metric of success. The winner, a model called gpt-5.6-sol, successfully found a buried piece of information two documents deep in the company’s files that was essential for sealing the deal, earning it a full score boost of +€4,583 MRR (monthly recurring revenue).
Meanwhile, a lesser-known contender, Kimi K3, also closed the deal but without the same depth of analysis. Its on-record reasoning was focused on avoiding impersonation, treating the manipulation attempt as a suspected fraud. In essence, it refused to engage in risky behaviors, earning high marks for integrity.
AI decision-making simulation platforms
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Cost of Discipline and the Reality of Performance
The experiment utilized a live, simulated software company with 13 synthetic employees operating in real-time, burning €105,000 monthly against a revenue of €2,300. Every day, the models had to make decisions—sometimes complex, sometimes deceptive—that could make or break the company’s success.
In this environment, the most thorough participant, Opus 4.8, with over 80 learned rules, demonstrated the importance of discipline. Despite its extensive analysis, it left a deal on the table and slipped on escalation procedures—showing that even the most comprehensive models can falter if they lack focus or discipline.
AI performance benchmarking software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What This Means for Business Technology
For owners and managers, the takeaway is clear: AI systems used in commercial settings must demonstrate more than language prowess. They need to show consistency, honesty, and strategic depth under pressure—traits that are often invisible in chat demos but are critical in real-world applications.
The leaderboard from the Crucible League illustrates this reality: the top scorer, gpt-5.6-sol, achieved a 95, nearly perfect score, by uncovering hidden facts and making decisive, honest actions. The second, Kimi K3, scored 93, just behind, with impeccable discipline and trustworthiness. These models prove that a focus on integrity and thoroughness pays off, not just clever language tricks.
Why Transparency Matters
Every decision in the experiment was recorded and made auditable, emphasizing the importance of transparency in AI management tools. When deploying AI in your home or business, it’s not enough for the system to perform well in demos; it must also be capable of handling real pressures without shortcuts or deception.
Firmulate’s live platform allows enterprises to run their own ‘wargames’—testing their AI workforce against realistic scenarios without risking their actual systems. This way, organizations can see how their AI would behave in critical moments, ensuring trustworthiness before full deployment.
Final Thoughts
The Crucible League highlights a crucial point: a minimal baseline of effort is not zero, but it’s also not enough. Effective AI models are those that can read deeply, stay honest under pressure, and deliver consistent results. As businesses increasingly rely on AI for decision-making, understanding what makes a trustworthy and effective system is more important than ever.
Visit firmulate.com/benchmarks.html to see live scores and learn how to run your own AI wargame—because knowing your AI’s true capabilities is the key to making smarter, safer business decisions.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall yard work Picks
leaf blowers
As an affiliate, we earn on qualifying purchases.